Transcript
Introducing Deep Hat Sift: A Self-Improving Model for AI at Scale
Introducing Deep Hat Sift: A Self-Improving Model for AI at Scale.
Kindo’s new System One decision model decides which events in a high-volume stream deserve an AI agent’s review and skips the rest, reducing LLM costs without giving up human control.
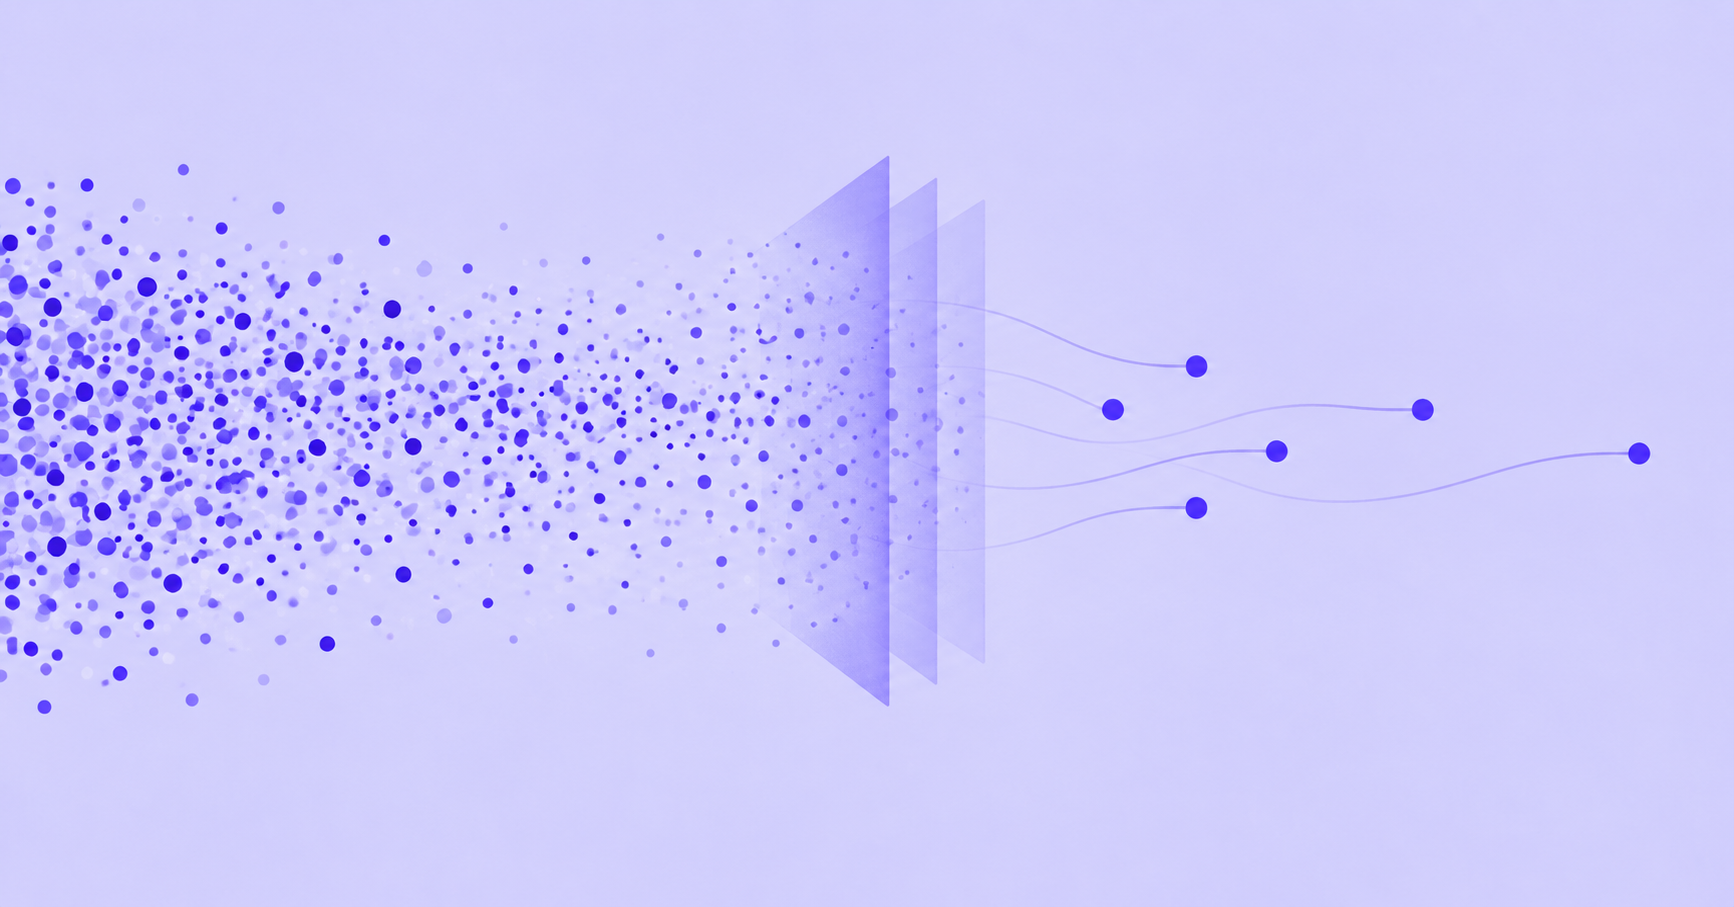
Today, we’re unveiling Deep Hat Sift, a self-improving System One decision model that learns which events in a high-volume stream need LLM review and skips the rest. There’s nothing like it available on the market. It gives IT, security, finance, and compliance teams a practical way to put intelligence to work on sources they previously could not afford to monitor.
System One models are the fast, inexpensive class of AI that answers yes or no rather than generating text. Cheap filters have always existed. The problem is trusting what they skip. Sift learns from the verdicts of the agent it serves, gets better with every decision, and leaves a person in charge of each threshold.
AI Triage Shouldn’t Be a Luxury
Event triage is one of the first tasks AI agents are taking on in production, but it gets expensive fast. On a busy SIEM, log platform or ticketing system, an LLM-powered agent reviews event after event, and often decides that nothing needs to happen. But each review still takes time and costs money. So, teams have been left with two options: they can pay the steep cost of having an LLM review every signal, or they can use a cheaper scoring model that isn’t reliable enough to decide what can safely be ignored.
Faced with that trade-off, many teams simply keep agents away from their busiest sources, even though those are often where agents could do the most valuable work.
It’s an unfair choice for enterprises to make. Today, we’re offering them a better choice.
Accuracy Meets Affordability
With Deep Hat Sift, a team assigns the model to one data source, one target agent, and one filtering task. Sift first runs in shadow mode, scoring every event while still sending every event to the agent and learning from its verdicts which events it dismisses from its verdicts. It then previews, on the customer’s own events, what it would filter. Only after a person approves a threshold with a written reason does Sift begin filtering. Agents run only on events that warrant it. The agent’s verdicts are the training signal, so there is no labeling project for the team to run and no retrained vendor model to wait for. That feedback loop is the recursive self-improvement: each verdict makes Sift better at the task it was assigned.
Deep Hat Sift is built so that security and operations teams can trust it with the decision to skip an event:
- Nothing is filtered until a person approves it, and two approvals precede activation.
- A measured sample of would-be-filtered events still reaches the LLM, unflagged, so the miss rate is always known rather than assumed.
- Every filtered event is on record, and every approval is logged with the person who made it and the reason.
- If the data quality drifts or triggers spike past a ceiling, Deep Hat Sift fails safely and returns to shadow mode on its own, sending everything to the LLM again.
- Deep Hat Sift never writes or runs generated code and has no write access to the sources it reads..
Deep Hat Sift also reports recall and miss rate against the LLM’s own verdicts, on live events, so each team sees how it performs on its own data.
Built for One Task
Deep Hat Sift is not a general-purpose model. Each Sift model becomes the expert on its own stream. A large enterprise can run hundreds of thousands of Sift models at once, each continuously improving on the task it was deployed to handle.
Deep Hat Sift adds great value by working in front of the sources engineers already triage: SIEM and EDR alerts, ticket and alert queues, system and network logs, monitoring tools such as New Relic, Splunk, and Datadog, and streaming systems such as Apache Spark and Kafka. Lead use cases include alert storms, alert and ticket triage, log streams, and reported-phishing triage, with real-time review of event streams for policy anomalies and fraud indicators for compliance and finance teams. It also runs entirely inside the customer's environment, including air-gapped, for defense and regulated industries, for greater control.
Expanding the Toolkit for Enterprise AI’s Next Chapter
Deep Hat Sift joins the Deep Hat family, Kindo’s models and add-ons for running the LLMs and agents an organization needs cost effective intelligence and fully under its own control.
Where Sift decides which events need LLM analysis, Deep Hat Attack gives security teams a model built for authorized offensive security testing, including work that requires privacy or that general-purpose AI lab models may either refuse because of safety filters or offer only at unaffordable rates.
Sift decides which events need LLM analysis. Attack supports security work that requires a purpose-built model and a human in the loop.
Most importantly, Deep Hat puts finance, IT, security, and compliance teams firmly in control of their own AI vision.
To learn more about Deep Hat Sift, read our press release here.